Updated October 19, 2026
What is Knowledge Distillation?
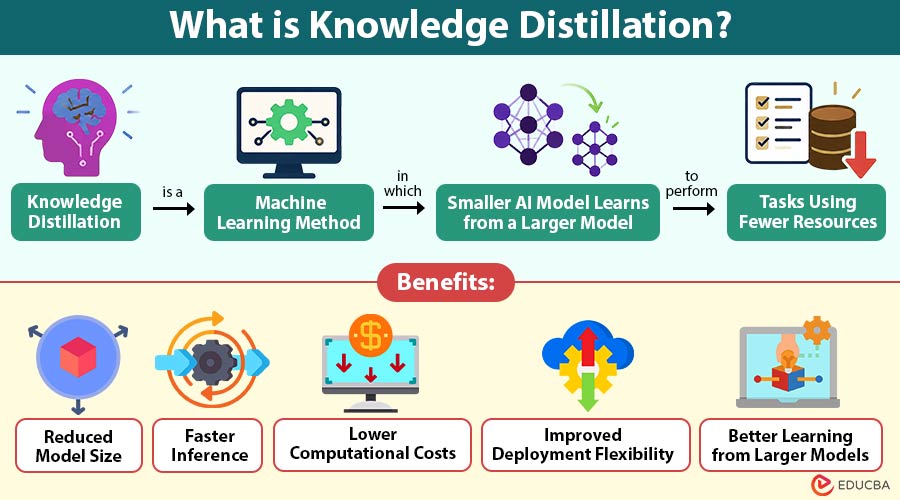
Knowledge distillation is a machine learning method in which a smaller AI model learns from a larger model to perform tasks using fewer resources.
Large AI models can handle difficult tasks and produce accurate results. However, they often need powerful computers, more memory, and higher processing power. This makes them expensive to run, especially on smaller devices.
Knowledge distillation helps solve this problem. It allows a smaller model, known as the student, to learn from a larger model, called the teacher. The student learns from the teacher’s predictions and the patterns it has already discovered. This helps the smaller model perform similar tasks without needing as much computing power.
For example, a large AI model may recognize different objects in images but require expensive hardware. A smaller model can learn from it and identify many of the same objects using fewer resources.
Knowledge distillation is commonly used in image recognition, language processing, speech recognition, and mobile AI applications.
Table of Contents:
Key Takeaways:
- Knowledge distillation lets smaller AI models learn from larger models, helping them perform similar tasks without needing as much memory or computing power.
- The larger model acts as a teacher, while the smaller student learns from its predictions and uses that information to improve its own performance.
- Smaller models often run faster and cost less to operate, making them useful for mobile applications and devices with limited computing power and memory.
- Developers use knowledge distillation in language processing, image recognition, speech recognition, and other applications where they need smaller AI models that work efficiently.
How Does Knowledge Distillation Work?
Knowledge distillation works by teaching a smaller AI model to learn from the results and information provided by a larger, trained model.
The process usually involves six steps.
1. Teacher Model Training
First, developers train a large AI model using relevant data. The model learns patterns and makes predictions that can later guide the student.
2. Student Model Selection
Developers then choose a smaller model that needs less memory and processing power. They consider how fast and accurate the final model should be during use.
3. Knowledge Transfer
The teacher shares its predictions and other useful information with the student. This helps the smaller model understand patterns it might otherwise miss during training.
4. Student Model Optimization
The student learns by comparing its predictions with the teacher’s results. It adjusts its settings to reduce mistakes and improve performance over time.
5. Performance Evaluation
After training, developers test the smaller model for accuracy, speed, and memory use. They compare the results with those of the larger teacher model.
6. Model Deployment
Developers can utilize the smaller model in mobile apps, cloud services, or devices with low memory and processing capacity once it performs well enough.
Types of Knowledge Distillation
There are three common types of knowledge distillation. Each type passes information from the teacher to the student in a different way.
1. Response-Based Knowledge Distillation
In response-based distillation, the student learns from the teacher’s final predictions. It uses these results to understand possible answers and improve its own prediction accuracy.
2. Feature-Based Knowledge Distillation
Feature-based distillation helps the student learn from patterns found inside the teacher model. This gives the smaller model more information than final predictions alone can provide.
3. Relation-Based Knowledge Distillation
Relation-based distillation teaches the student how different pieces of information are connected. It focuses on learning relationships between data rather than simply copying the teacher’s answers.
Common Knowledge Distillation Techniques
Developers use different techniques to help smaller AI models learn from larger ones.
1. Soft Label Distillation
The student learns from the teacher’s probability scores rather than just the correct answers. These scores show how likely different answers are and provide more information for learning.
2. Logit Distillation
This method teaches the student using the teacher’s raw prediction scores. These scores contain useful information that helps the smaller model learn how the teacher makes predictions.
3. Intermediate Layer Distillation
The student learns from information found inside the teacher’s network layers. This helps it recognize useful patterns instead of relying only on the final prediction.
4. Self-Distillation
A model learns from its own earlier results or previous versions. This method can improve its performance without always needing another larger model to act as a teacher.
5. Online Distillation
In online distillation, models learn together during training. They share useful information instead of waiting for one model to finish training before another begins.
Examples of Knowledge Distillation
Knowledge distillation helps developers build AI systems that can perform tasks without expensive or powerful hardware.
| Application | Teacher Model | Student Model Objective |
| Image Recognition | Large image recognition model | Identify images faster |
| Natural Language Processing | Large language model | Understand text efficiently |
| Speech Recognition | Advanced speech model | Convert speech into text faster |
| Mobile Applications | Large AI model | Use less memory |
| Autonomous Systems | Advanced visual processing model | Process information quickly |
Benefits of Knowledge Distillation
Knowledge distillation offers several benefits, especially when businesses want AI models that are easier and less expensive to use.
1. Reduced Model Size
Smaller AI models require less storage and memory, making them easier to run on smartphones, computers, and other devices with limited hardware resources.
2. Faster Inference
Smaller models often produce results faster because they require fewer calculations. This helps applications respond faster when users need immediate answers.
3. Lower Computational Costs
Smaller AI models usually require less processing power. This can help companies save money when their applications handle large numbers of requests every day.
4. Improved Deployment Flexibility
Compact AI models can work on different devices, including smartphones and embedded systems. This makes it easier to use AI where powerful computers are unavailable.
5. Better Learning from Larger Models
Student models can learn useful patterns from larger models instead of starting from scratch. This may help them achieve better training results.
Challenges of Knowledge Distillation
Knowledge distillation can make AI models smaller and faster, but it also comes with certain challenges.
1. Performance Degradation
A smaller model may not perform as well as its teacher, especially on difficult tasks that require more information, memory, or complex decision-making.
2. Teacher Model Dependency
The student depends on the information the teacher provides. If the teacher makes incorrect predictions, the smaller model may learn those mistakes during its training.
3. Training Complexity
Developers need to choose suitable models and training methods. Finding the right settings can take time, especially when balancing accuracy with processing speed.
4. High Initial Training Costs
Although smaller models may be cheaper to run, training them can still be expensive because developers need computing resources, teacher predictions, and repeated testing.
5. Knowledge Transfer Limitations
Some information may be difficult for a smaller model to learn. This happens when the teacher is much more complex or uses a very different structure.
Difference Between Knowledge Distillation and Model Compression
The table below highlights the key differences between the two:
| Basis | Knowledge Distillation | Model Compression |
| Meaning | Transfers learning from one model to another | Makes AI models smaller or more efficient |
| Approach | Uses teacher and student models | Uses different methods to reduce resource needs |
| Techniques | Soft labels, feature learning, relation learning | Pruning, quantization, distillation |
| Main Focus | Helping a smaller model learn | Reducing model size and resource use |
| Requirements | Usually needs a teacher model | Does not always need a teacher model |
Best Practices for Knowledge Distillation
Developers can improve knowledge distillation results by following a few key practices during training and testing.
1. Select a Suitable Teacher
Choose a teacher model that performs well on the required task. A reliable teacher provides better information to the student and helps reduce mistakes during learning.
2. Define Performance Requirements
Decide how accurate and fast the student should be before training. Also consider available memory, processing power, and the devices where it will be used.
3. Choose Appropriate Techniques
Use a distillation method that suits the task and models involved. The right approach depends on available data and what the student needs to learn.
4. Optimize Training Parameters
Adjust training settings such as learning rate, temperature, and loss weights. Testing different values can help the student learn more effectively from the teacher model.
5. Evaluate Model Performance
Test the smaller model using real examples and suitable devices. Compare its speed, accuracy, and memory use with the teacher before deploying it.
Final Thoughts
Knowledge distillation is a useful way to make AI models smaller and easier to run. Instead of training a smaller model from scratch, developers let it learn from a larger, trained model. This can reduce memory use, lower computing costs, and speed up processing. Smaller models can also bring AI features to devices that cannot handle large systems. However, the results depend on how well the student learns from its teacher. Proper training and testing are important to make sure the smaller model works as expected.
Frequently Asked Questions (FAQs)
Q1. What is the main purpose of knowledge distillation?
Answer: The main purpose is to help smaller AI models learn from larger models so they can perform useful tasks with less memory and computing power.
Q2. Does knowledge distillation always improve model accuracy?
Answer: No. A smaller model may not always match the teacher’s accuracy. Results depend on the training data, model design, and quality of the information transferred.
Q3. Can knowledge distillation be used for large language models?
Answer: Yes. Developers can use large language models to train smaller versions that handle selected language tasks with lower memory requirements and reduced computing costs.
Q4. Is knowledge distillation a type of model compression?
Answer: Yes. Knowledge distillation is one method of model compression. It helps create smaller AI models by transferring useful information from larger models during training.
Recommended Articles
We hope that this EDUCBA information on “Knowledge Distillation” was beneficial to you. You can view EDUCBA’s recommended articles for more information.