Updated October 6, 2026
What is Model Quantization?
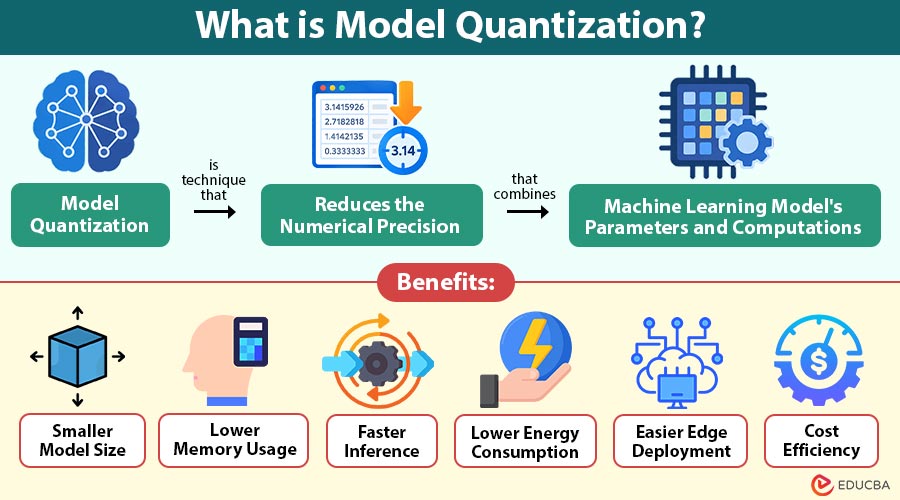
Model quantization is technique that reduces the numerical precision of a machine learning model’s parameters and computations. It converts high-precision values, such as 32-bit floating-point numbers, into lower-precision formats such as 16-bit, 8-bit, or 4-bit representations. This can reduce model size, memory usage, and computational requirements while helping maintain acceptable performance.
Quantization is widely used when deploying artificial intelligence models on devices and systems with limited computing resources. It is especially useful for edge AI, mobile applications, embedded systems, and efficient large language model deployment.
Table of Contents:
Key Takeaways:
- Model quantization reduces numerical precision to make machine learning models smaller and more efficient.
- It can lower memory usage, computational requirements, energy consumption, and inference latency during deployment.
- Quantization enables efficient AI deployment on smartphones, edge devices, embedded systems, and other resource-constrained environments.
- Quantization may reduce accuracy, so testing and hardware compatibility checks are essential before deployment.
How Does Model Quantization Work?
Model quantization maps values from a higher-precision numerical range to a smaller set of representable values. A quantization method typically uses a scale factor and, depending on the method, a zero-point to transform floating-point values into lower-precision values.
For example, suppose a model contains weights represented using FP32. A quantization process may convert those weights into INT8 values. During inference, the system can perform calculations using the quantized representation or convert values when necessary.
The process generally involves:
1. Identifying Model Values
The system identifies weights, activations, biases, and other numerical components that can be converted to lower-precision representations.
2. Determining Numerical Ranges
The quantization process analyzes value ranges and statistical distributions to establish appropriate scaling parameters for accurate numerical mapping.
3. Mapping Values
Higher-precision floating-point values are mathematically mapped to corresponding lower-precision values using defined scale factors and zero-points.
4. Storing Quantized Values
The model stores weights or activation values using fewer bits. This reduces memory use and can improve processing efficiency.
5. Running Inference
During inference, the quantized model uses supported hardware operations to process inputs faster and more efficiently.
6. Evaluating Accuracy
Developers compare the quantized model with the original model. This helps measure any changes in accuracy and check whether the model still meets the required performance.
Types of Model Quantization
Below are the main types of model quantization, each offering a different approach to reducing numerical precision and improving model efficiency.
1. Post-Training Quantization
This method is applied after the model has been trained. It converts model parameters or calculations to lower precision without requiring the model to be fully retrained.
2. Quantization-Aware Training
This method considers the effects of quantization during model training. It helps the model adjust to lower precision while maintaining better accuracy.
3. Dynamic Quantization
This method stores model weights in lower precision. It adjusts the activation values during inference based on the input data.
4. Static Quantization
This method sets quantization values before deployment. It uses sample data to determine the required activation ranges, which remain fixed during inference.
5. Weight-Only Quantization
This method reduces the precision of model weights while keeping other parts of the model at higher precision. It helps reduce memory usage during deployment.
Model Quantization Process
The model quantization process typically follows several stages:
Step 1: Select the Model
Developers first identify the trained model to optimize. They also determine the target device, framework, and hardware capabilities.
Step 2: Identify Quantizable Components
Developers analyze the model’s weights, activations, and operations to determine which components can be represented with lower precision.
Step 3: Choose Precision
Developers select an appropriate numerical format, such as FP16, INT8, or INT4, depending on the model and deployment requirements.
Step 4: Calibrate the Model
For approaches that require calibration, pass representative input data through the model to understand activation ranges and determine suitable quantization parameters.
Step 5: Convert the Model
Convert the selected components into the desired lower-precision representation.
Step 6: Test Performance
Evaluate the quantized model for accuracy, latency, memory usage, and computational performance.
Step 7: Deploy the Optimized Model
After testing, you can deploy the quantized model to the target environment, such as cloud server, smartphone, edge device, or embedded system.
Benefits of Model Quantization
Model quantization provides several benefits for AI deployment.
1. Smaller Model Size
Using fewer bits to represent model parameters reduces the model size. This makes models easier to store, share, and deploy on devices with limited storage.
2. Lower Memory Usage
Quantized models use less memory to store model parameters and computations. This makes them suitable for devices with limited memory.
3. Faster Inference
Lower-precision calculations can run faster on hardware that supports quantized operations. This can help reduce the time needed to process AI tasks.
4. Lower Energy Consumption
Smaller models and simpler calculations can reduce the amount of computing power needed. This can help lower energy use during model inference.
5. Easier Edge Deployment
Quantization makes AI models easier to run on smartphones, IoT devices, cameras, industrial systems, and other devices with limited computing resources.
6. Cost Efficiency
Quantized models can require fewer computing resources. This can help reduce infrastructure needs and lower the cost of running AI models.
Limitations of Model Quantization
Despite its benefits, model quantization has several limitations.
1. Potential Accuracy Loss
Reducing numerical precision can cause small errors in model calculations. These errors may affect the accuracy of predictions.
2. Hardware Dependency
The performance of a quantized model depends on the hardware. The hardware must support the selected numerical format and quantized operations.
3. Additional Testing
Developers need to test the quantized model carefully. This helps ensure that the model maintains acceptable accuracy and performance.
4. Implementation Complexity
Some models may require special quantization methods, calibration data, or additional optimization steps.
5. Not Every Model Benefits Equally
Quantization does not improve every model in the same way. Its effects depend on the model architecture, sensitivity to numerical changes, workload, and deployment environment.
Difference Between Model Quantization and Model Pruning
The following table highlights the key differences between model quantization and model pruning:
| Basis | Model Quantization | Model Pruning |
| Main approach | Reduces numerical precision | Removes selected parameters or connections |
| Primary target | Representation of values | Model structure |
| Model size | Reduced through lower-precision representation | Reduced by removing parameters |
| Accuracy impact | May introduce numerical errors | May remove information from the model |
| Common use | Efficient inference and deployment | Reducing unnecessary model parameters |
Example of Model Quantization
Suppose an AI image-classification model uses FP32 weights and requires 400 MB of memory. By converting the weights to INT8, the model may require only about 100 MB while maintaining similar prediction accuracy. This makes the model faster and easier to deploy on mobile and edge devices.
Final Thoughts
Model quantization optimizes machine learning models by reducing numerical precision, helping lower model size, memory usage, computational requirements, and inference latency. Techniques such as post-training, quantization-aware, dynamic, static, and weight-only quantization offer different efficiency approaches. Effectiveness depends on the model architecture, hardware compatibility, selected precision, and required deployment accuracy.
Frequently Asked Questions (FAQS)
Q1. Why is model quantization important for large language models?
Answer: Model quantization can significantly reduce the memory footprint of large language models, making them easier to run on GPUs, personal computers, and edge devices.
Q2. Does quantization change the architecture of a machine learning model?
Answer: Generally, quantization does not change the model’s fundamental architecture. Instead, it changes how numerical values are represented and processed.
Q3. Which precision is commonly used for model quantization?
Answer: Common precision formats include FP16, INT8, and INT4. The appropriate choice depends on the model, hardware, and required accuracy.
Q4. Can quantized models be used for real-time applications?
Answer: Yes. Quantized models can support real-time applications when the target hardware provides optimized low-precision operations and sufficient computational performance.
Recommended Articles
We hope that this EDUCBA information on “Model Quantization” was beneficial to you. You can view EDUCBA’s recommended articles for more information